Business · AI Products
Focus on AI Innovation,
Not on AI Infrastructure
Heterogeneous GPU and NPU hardware, model serving, deployment, and monitoring: every layer of infrastructure an AI service needs runs from a single Control Plane. AURDA AI Infra is a Kubernetes-based PaaS that spans on-premise and multi-cloud environments. AURDA AI Infra handles resources and serving; AURDA AI Gateway handles access and control. Deploy either on its own, or both together as a Suite.
Key Features
Infrastructure Operations, Finished On Screen
These are the actual product screens. GPU allocation, deployment, and monitoring all run from one console.
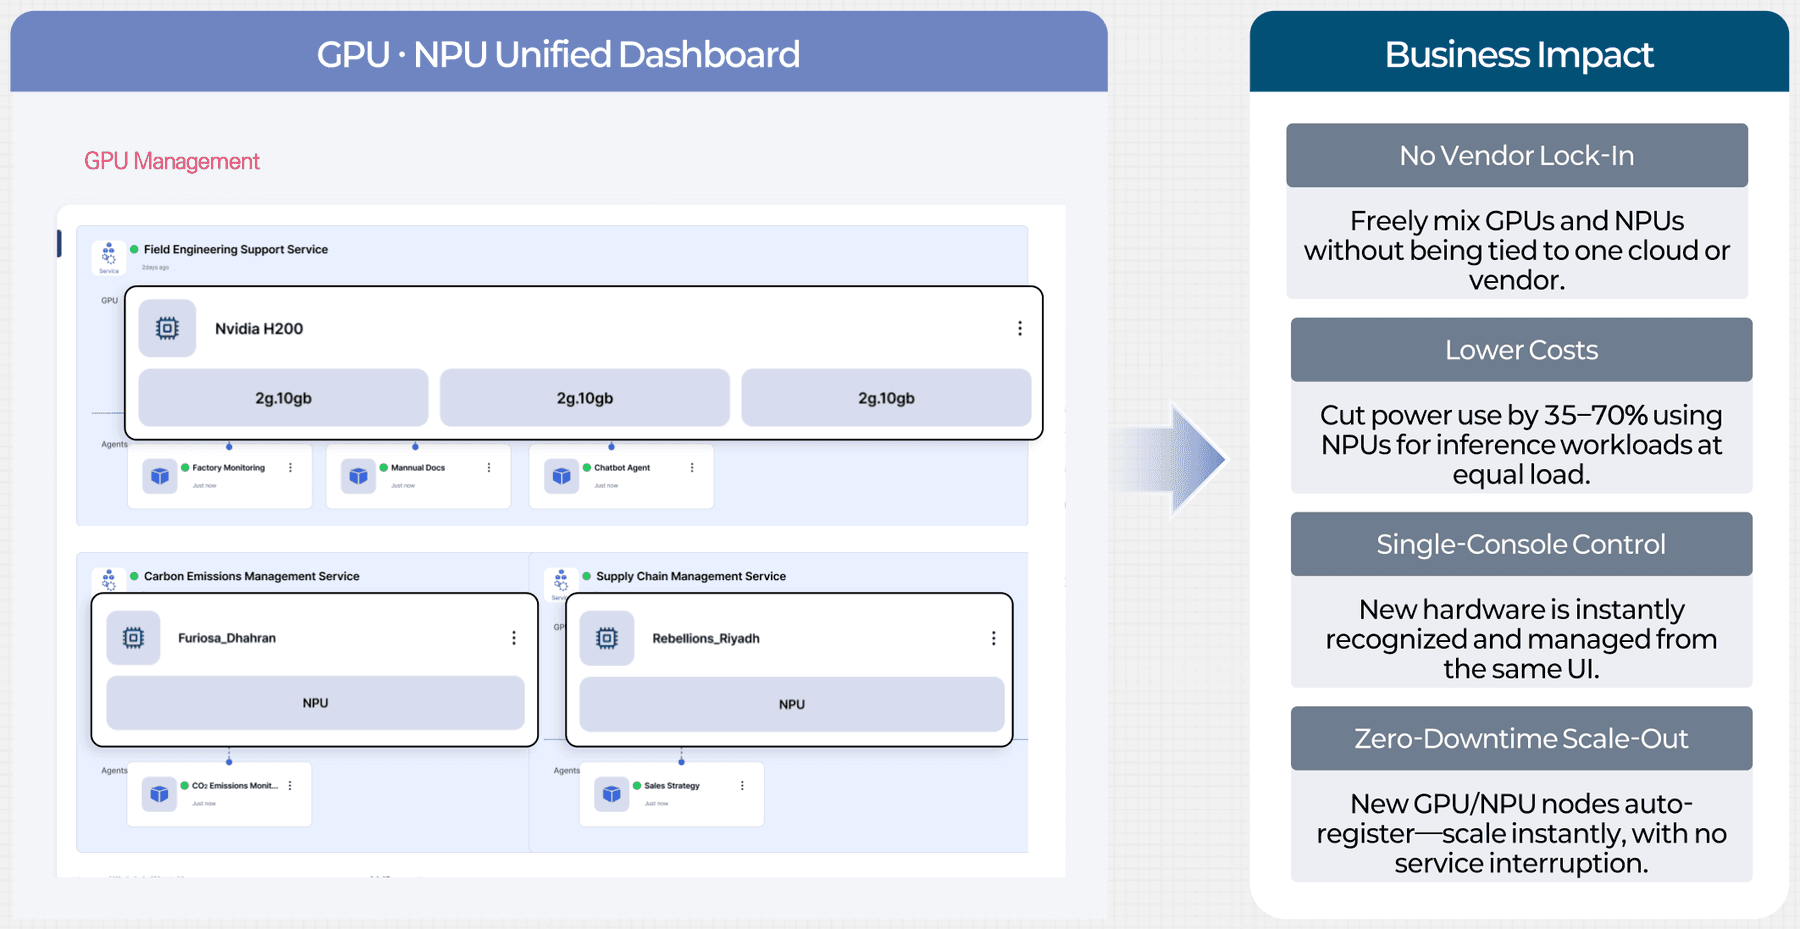
GPU·NPU Console
NVIDIA GPUs and Korean NPUs on One Screen
Run NVIDIA H200 GPUs alongside FuriosaAI and Rebellions NPUs from a single console. Pick the best hardware for each workload without vendor lock-in. New nodes are detected automatically and join with no downtime.
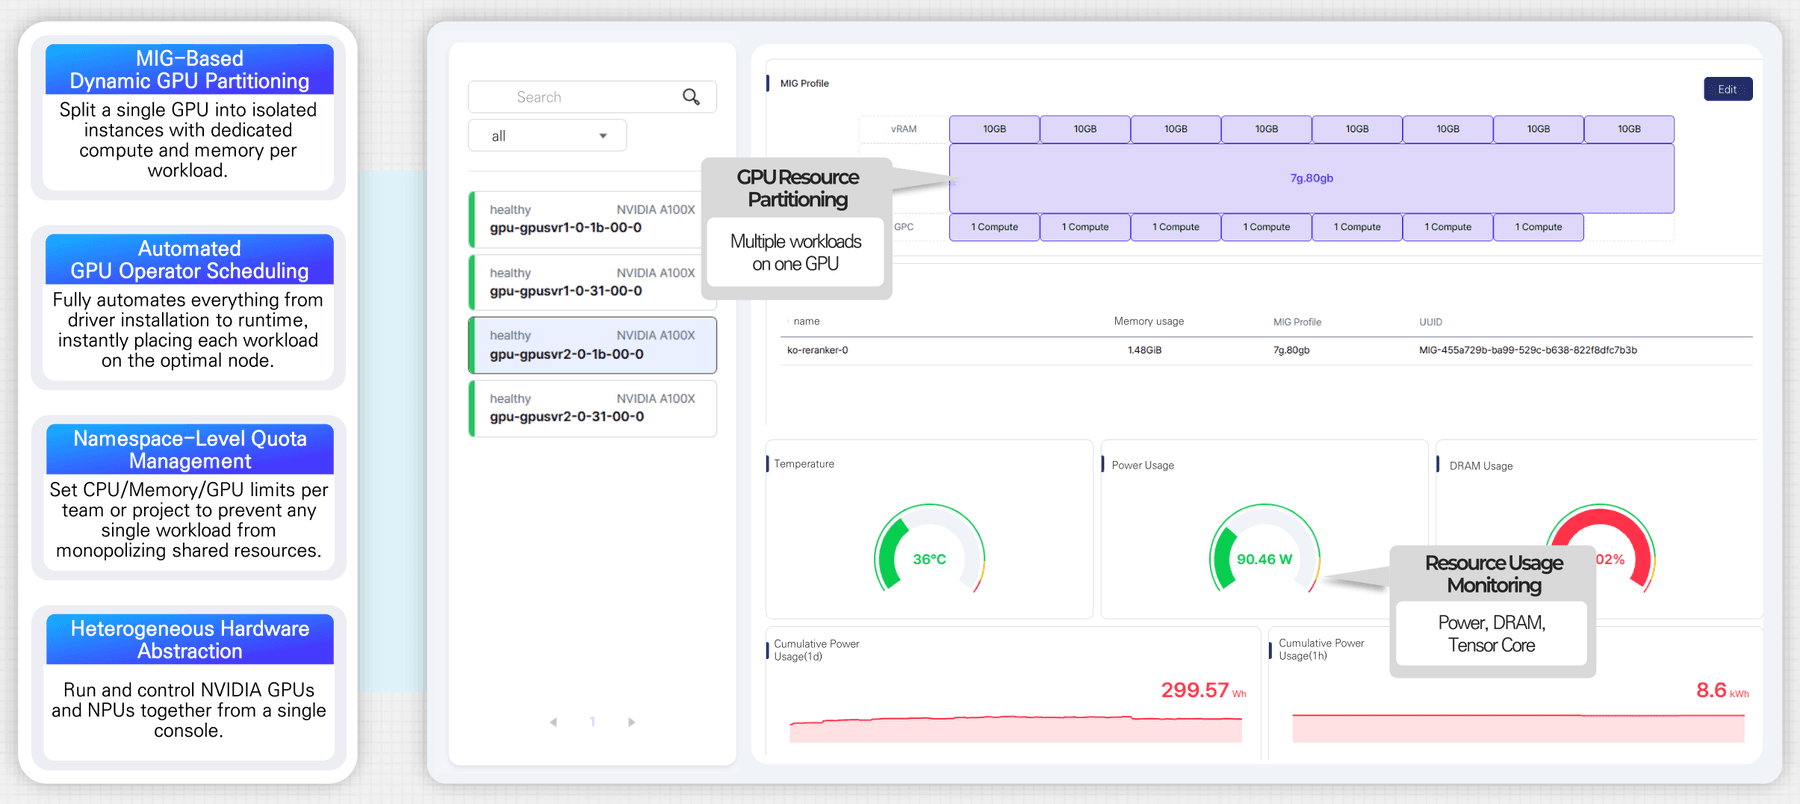
MIG Partitioning
Split One GPU Across Workloads, Precisely
MIG divides a high-performance GPU into up to seven independent instances, physically isolating compute and memory. GPU state is tracked live, down to temperature, power draw, and DRAM utilization.
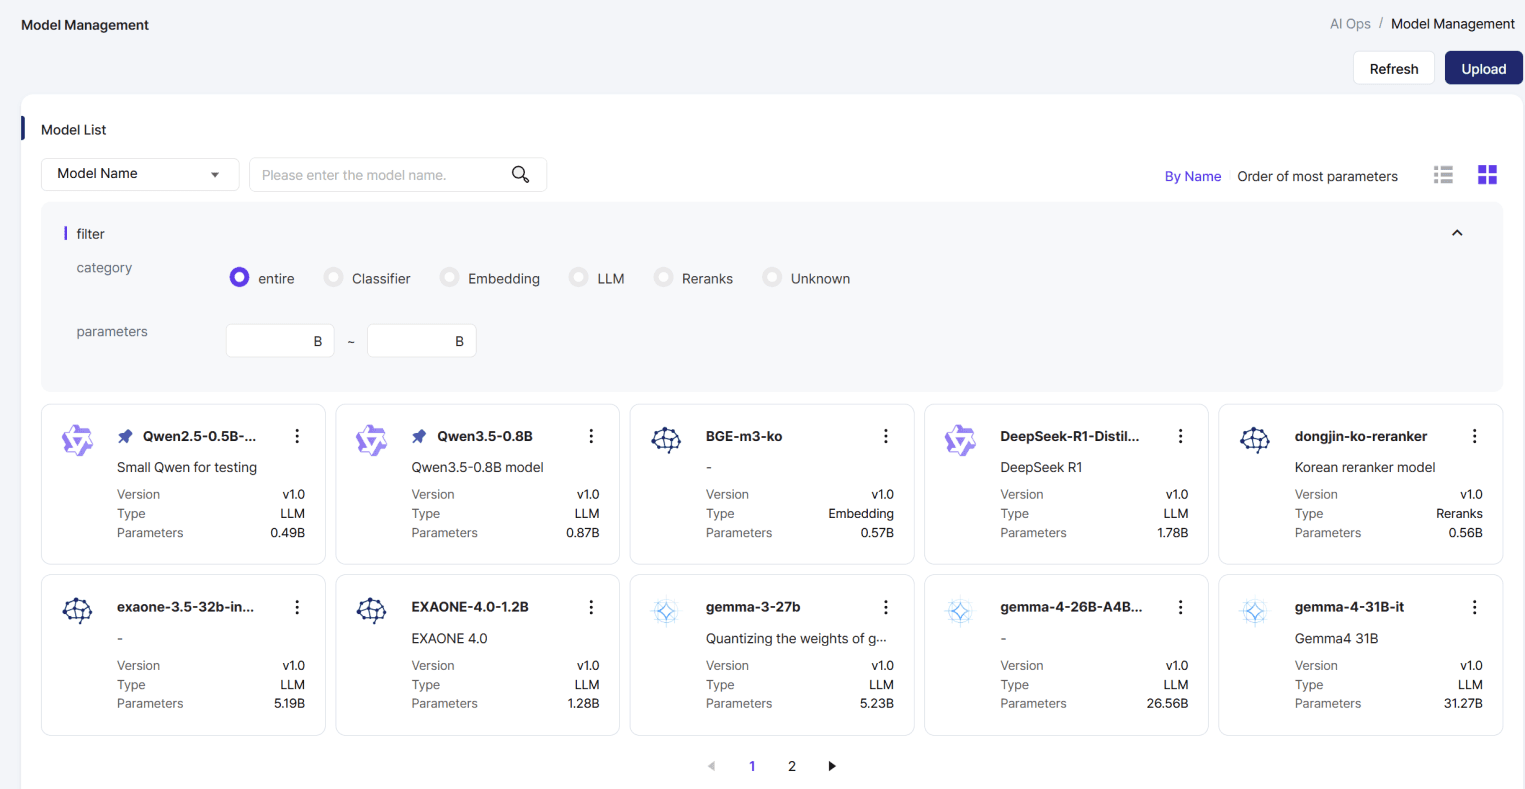
Model Serving
Deploy an LLM in One Click
Choose a model, GPU resources, and a runtime, and the console deploys it immediately. The vLLM high-performance inference engine is supported. In air-gapped networks, models load directly from an internal repository, so the service runs with no external internet.
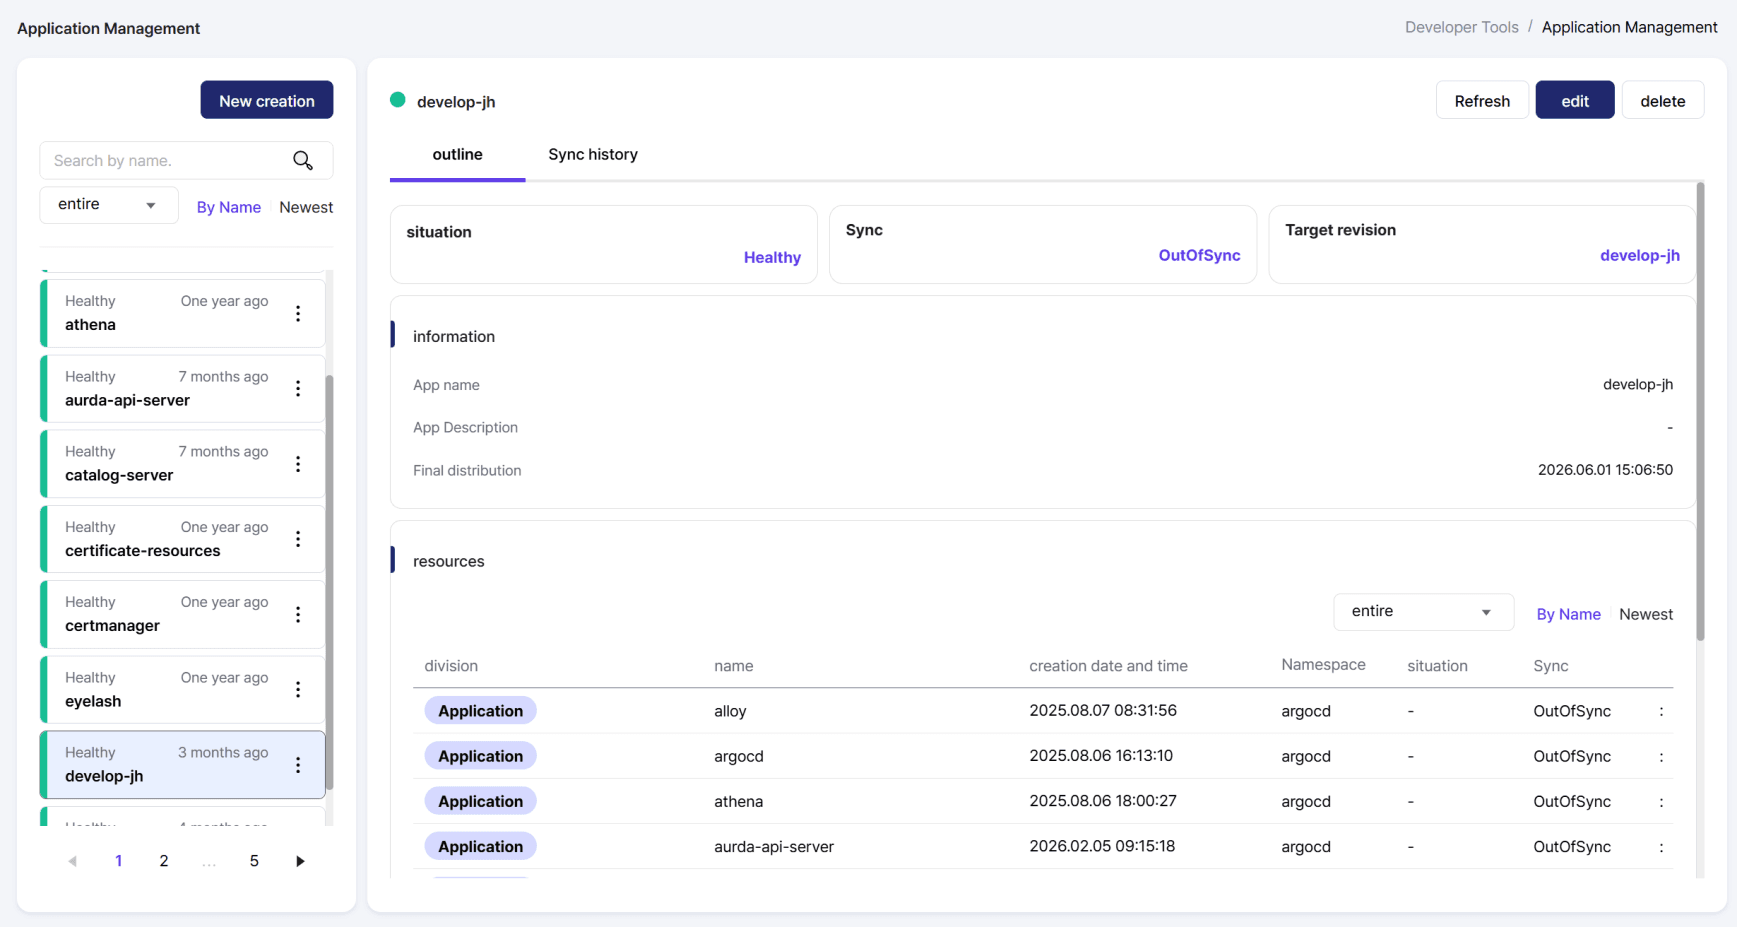
GitOps
Infrastructure and Deployment as Code, Rollback Anytime
Built on ArgoCD, the state defined in Git is applied to the cluster automatically. Drift between the Git definition and the live state is detected at once, and a failure restores to the previous version immediately.
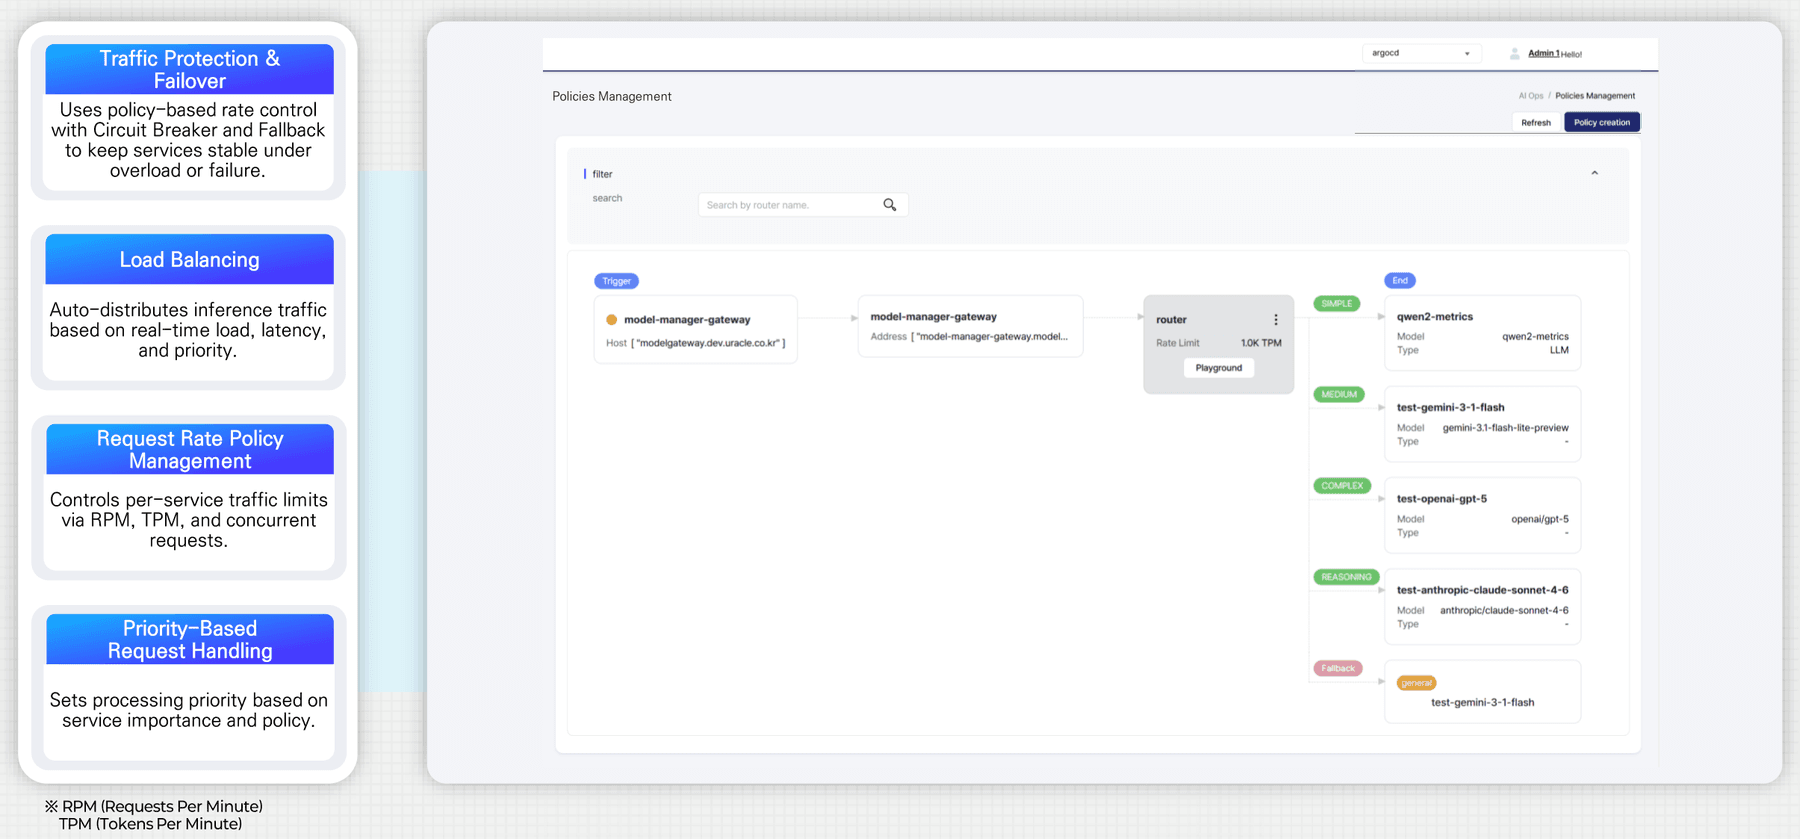
Autoscale
Serving Instances Scale with the Load
Define scaling conditions on metrics, and when load spikes, serving instances scale out automatically and requests spread across the available capacity. Unifying internal models and external LLMs behind one API and distributing traffic is the job of AURDA AI Gateway.
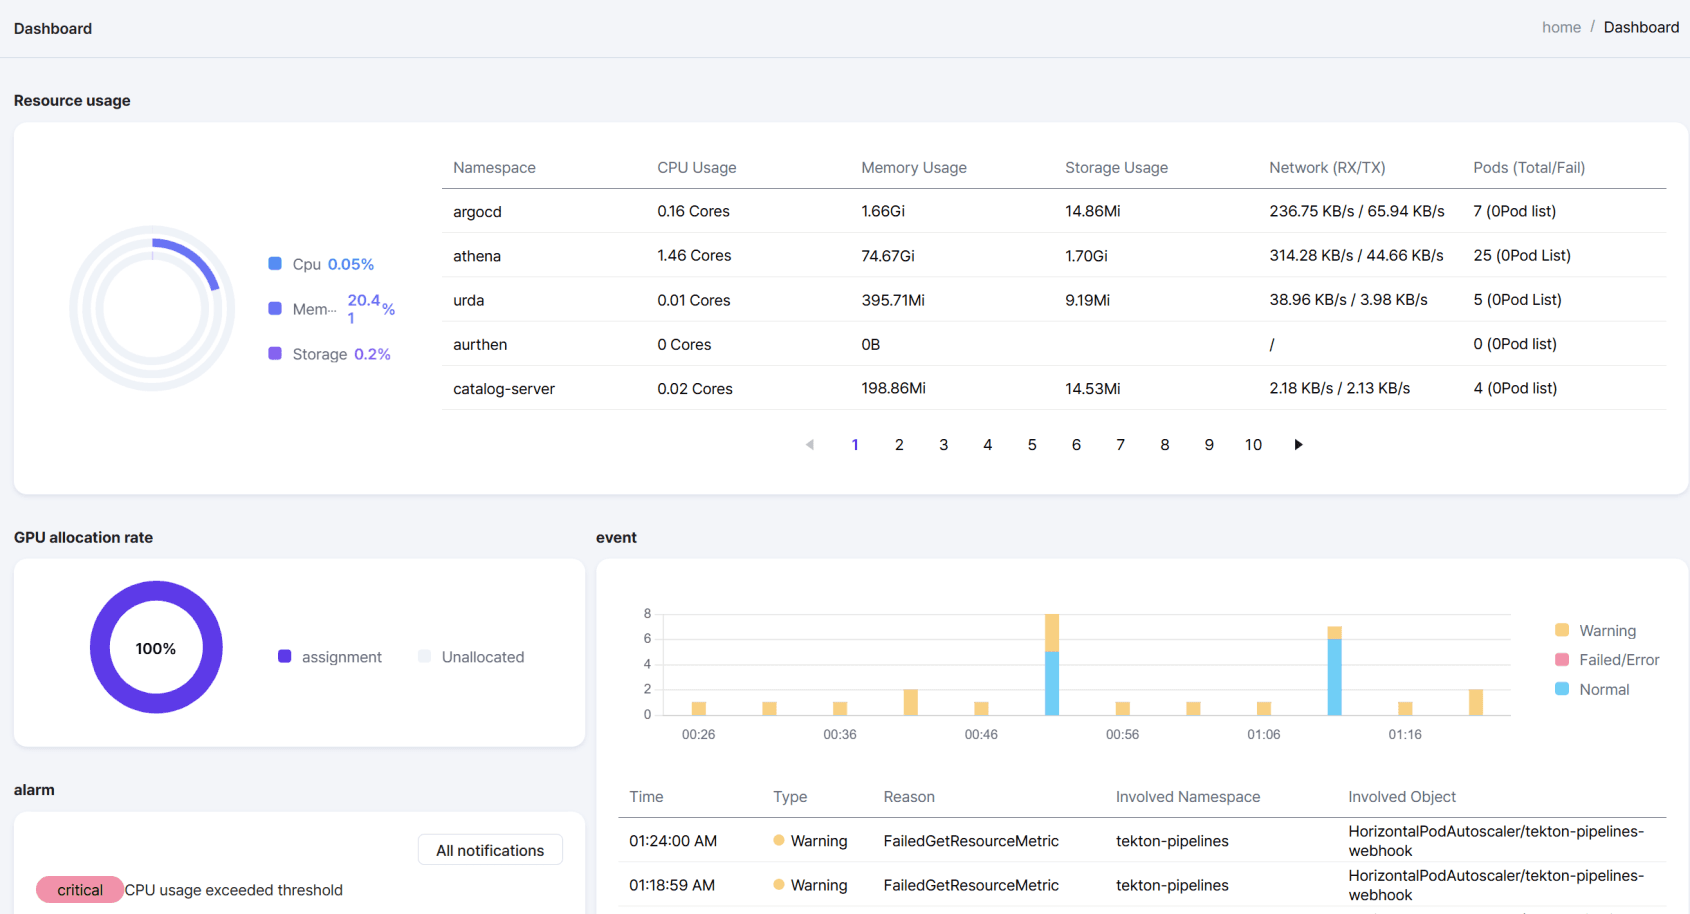
Observability
One Dashboard, from Infrastructure to LLM Inference
Track GPU utilization, temperature, and power alongside LLM performance metrics such as TTFT and TPS on a single dashboard. Centralized logging on Loki and threshold-based live alerts shorten incident response time.
Platform
Defining the Standard for AI Infrastructure Operations
From container virtualization to security, everything AI operations require sits on top of Kubernetes orchestration.
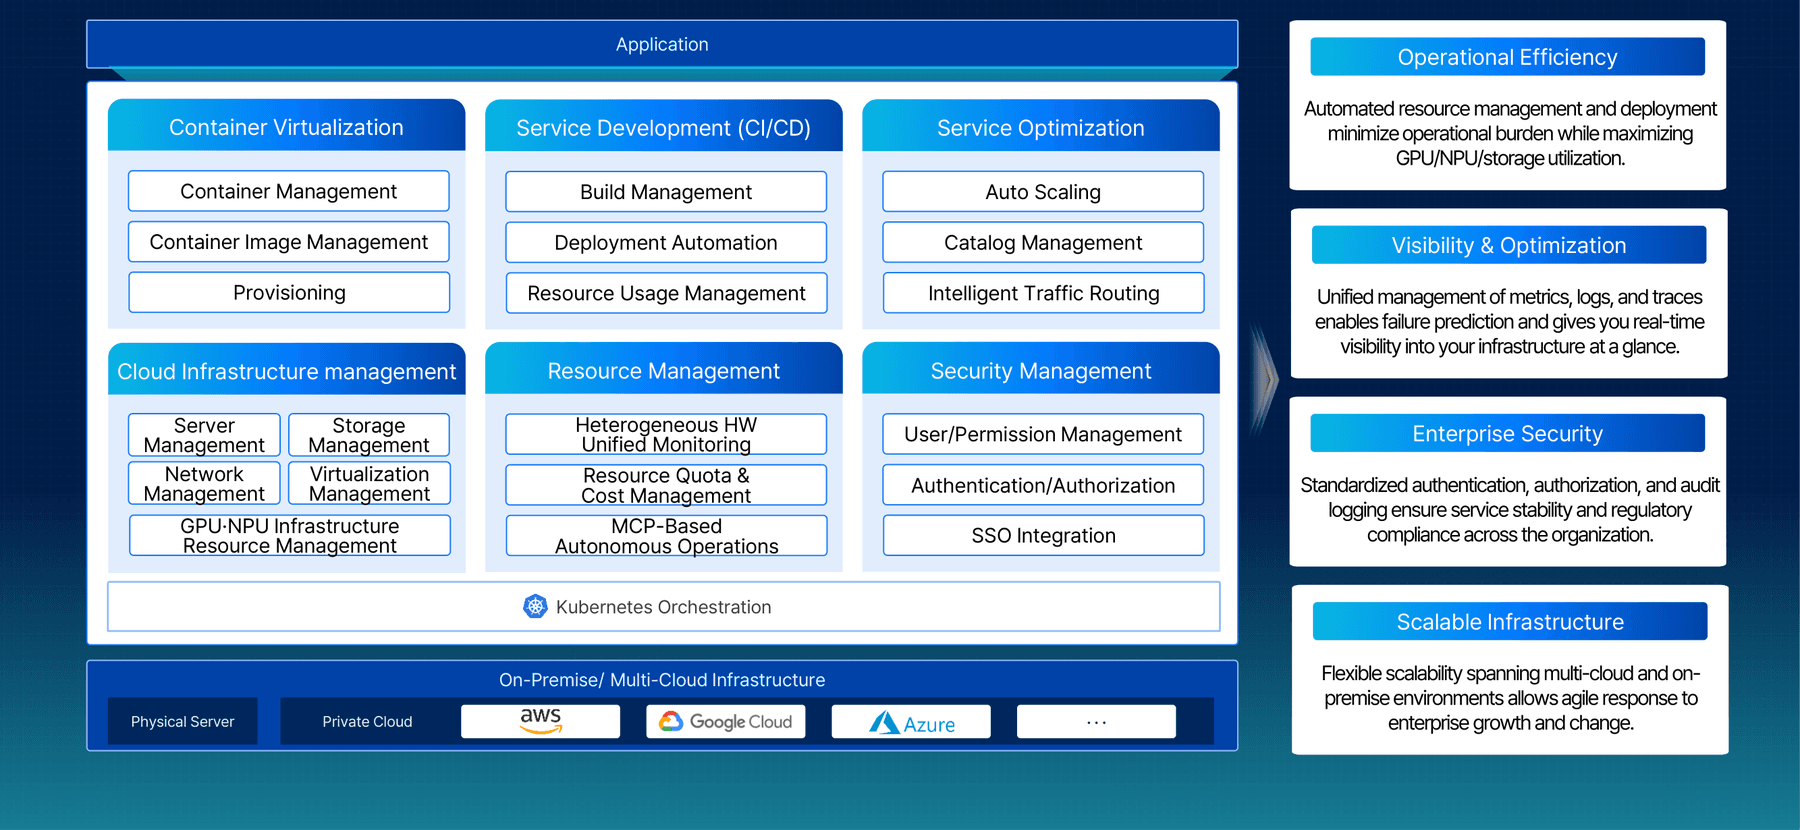
Architecture
Six Management Domains, One Platform
Container virtualization, service development (CI/CD), service optimization, cloud infrastructure, resource management, and security management. It is one Kubernetes-based structure covering on-premise and multi-cloud.
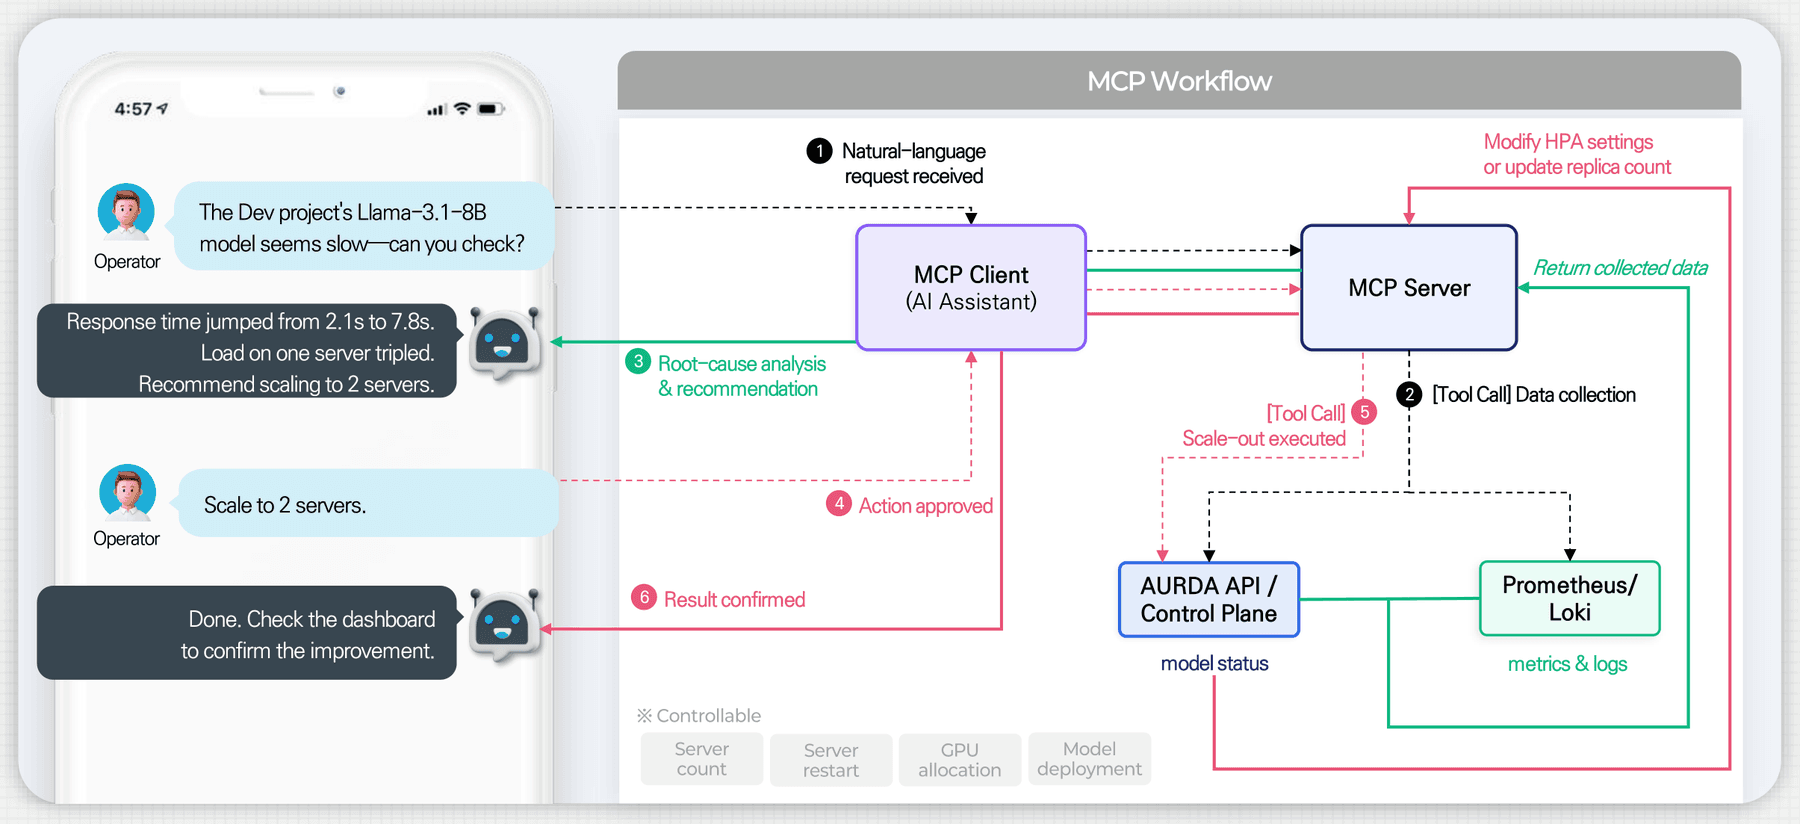
Agentic ChatOps
"Scale That to Two Servers": Infrastructure Run by Conversation
An MCP-based AI Agent interprets natural-language commands and carries them out, from root-cause analysis through to scale-out. Incident response gets shorter, and repetitive operations work ends in a conversation.
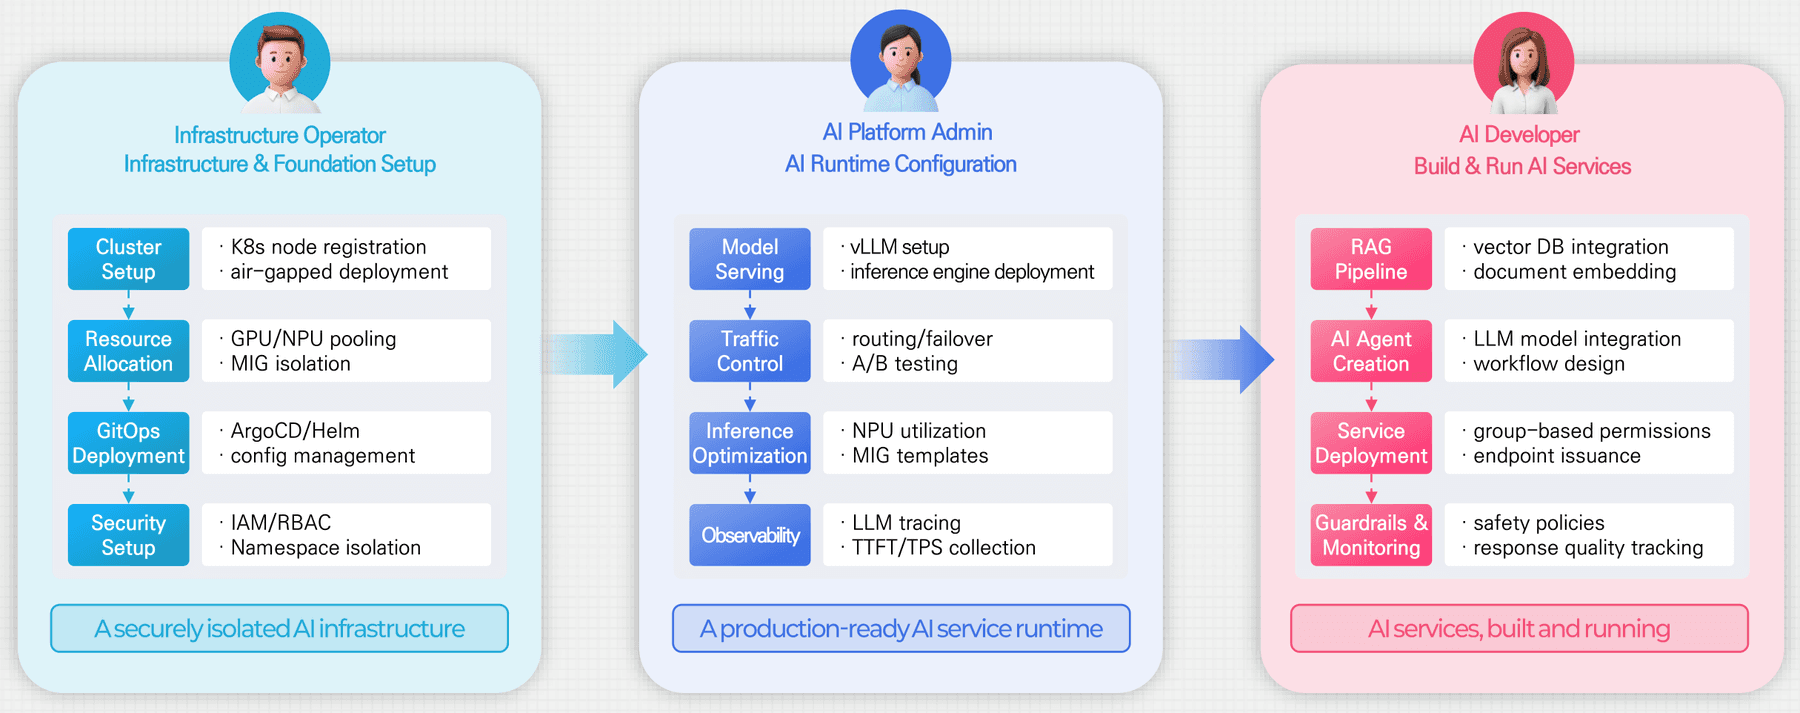
Role-based Workflow
Operators, Administrators, Developers: Each Role Has Its Flow
Cluster installation and security setup for the infrastructure operator. Model serving and inference tuning for the platform administrator. RAG and Agent development for the AI developer. Each operating flow is designed into the platform.
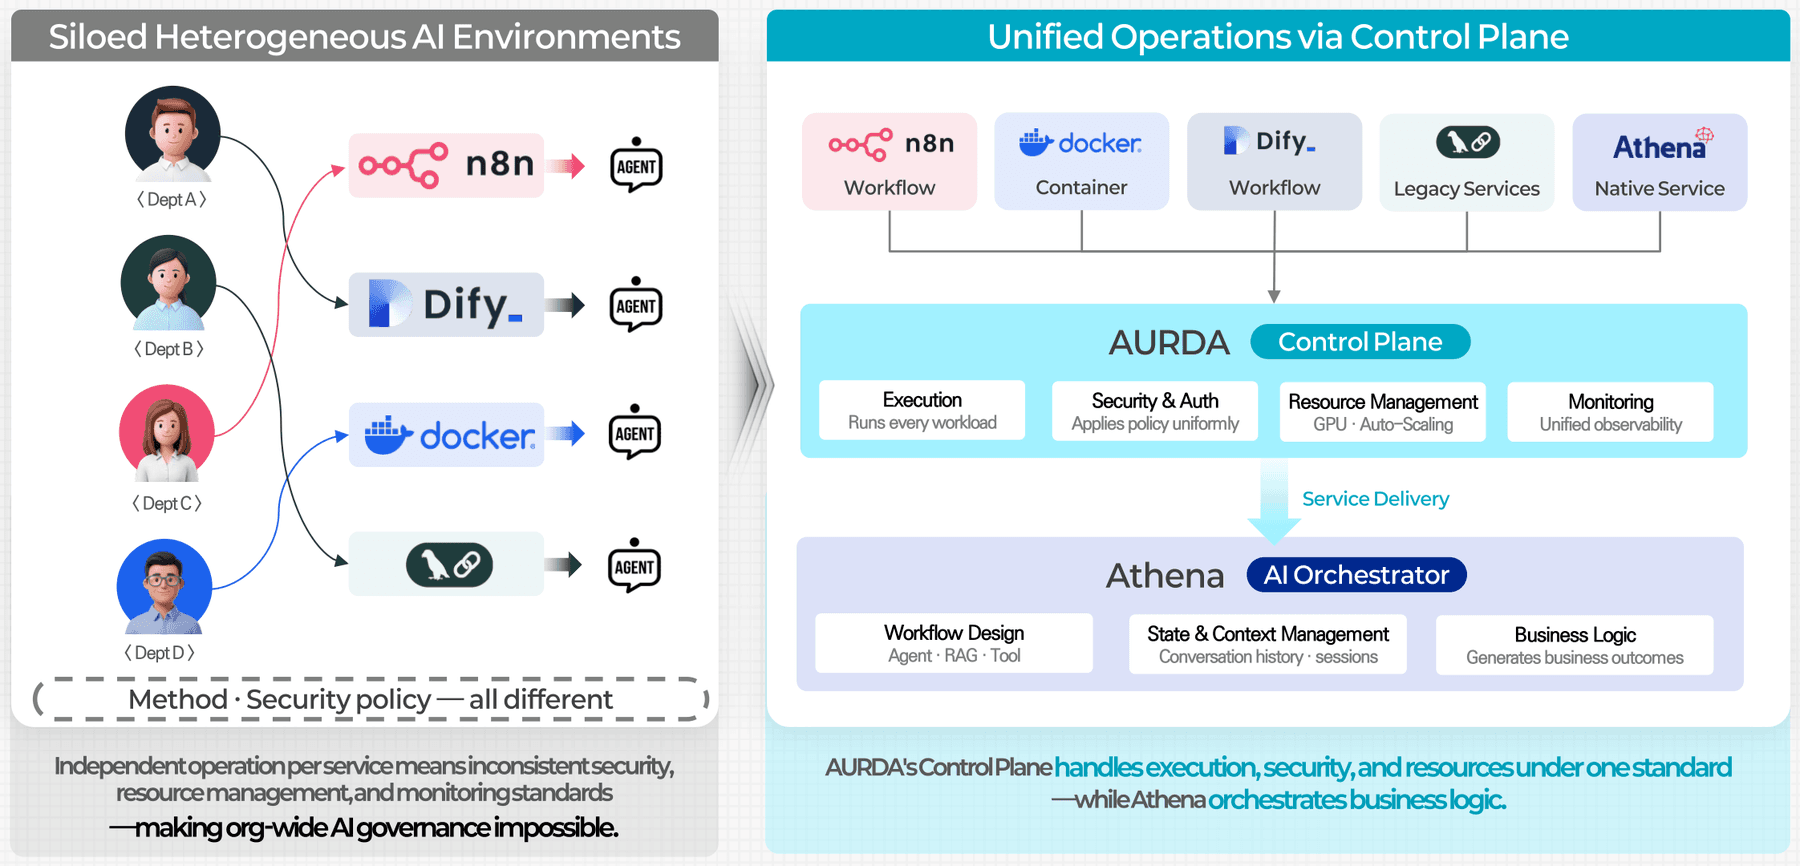
Universal AI Runtime
n8n, Dify, Docker: Heterogeneous Workloads, Unified
The AURDA Control Plane executes, secures, and monitors the workflows, containers, and legacy Agents scattered across departments against a single standard. That is what makes enterprise-wide AI governance possible.
Architecture
The Resource Layer of the Enterprise AI OS
Beneath AI Portal, AI Studio, and AI Gateway, AURDA AI Infra runs the accelerators and the serving.
Enterprise AI OS
Use, Build, Control, Resources: The Bottom of Four Layers
AI Portal (use and approval), AI Studio with Athena (Agent lifecycle), and AURDA AI Gateway (execution and governance) run above. AURDA AI Infra runs resources and serving on physical servers, cloud, NVIDIA GPUs, and Korean NPUs.
Disaggregated Inference
Reading Documents and Generating Answers on Separate Resources
Input processing (prefill) is compute-heavy; answer generation (decode) is memory-heavy. Splitting the two stages across separate accelerator pools and scaling each on its own raises GPU utilization and lowers power.
Why AURDA AI Infra
No Vendor Lock-In, and Resource Efficiency That Wins
Heterogeneous GPU and Korean NPU resources, model serving, and Agent serving are managed together, cutting AI infrastructure cost and operational load.
| Feature | Global commercial solutions | Self-built open source | AURDA AI Infra |
|---|---|---|---|
| Heterogeneous hardware | Centered on the NVIDIA GPU ecosystem | Configured device by device | Unified GPU and Korean NPU control, vendor-neutral |
| Partitioning and efficiency | Scheduling-centric; fine partitioning configured separately | Basic scheduling only | Dynamic MIG partitioning and quota management raise utilization |
| Scope | Workload scheduling | Assembled from individual tools | Model serving through Agent serving, in one platform |
| Operations | Console, run by specialists | Heavily dependent on specialists | Agentic ChatOps natural-language control lightens operations |
Qualitative comparison based on our products, October 2026Disaggregated inference serving: inference resources are split, allocated, and scaled separately for the input (prefill) and generation (decode) stages.
Customer Story
AURDA, Proven in the Field
KODATA
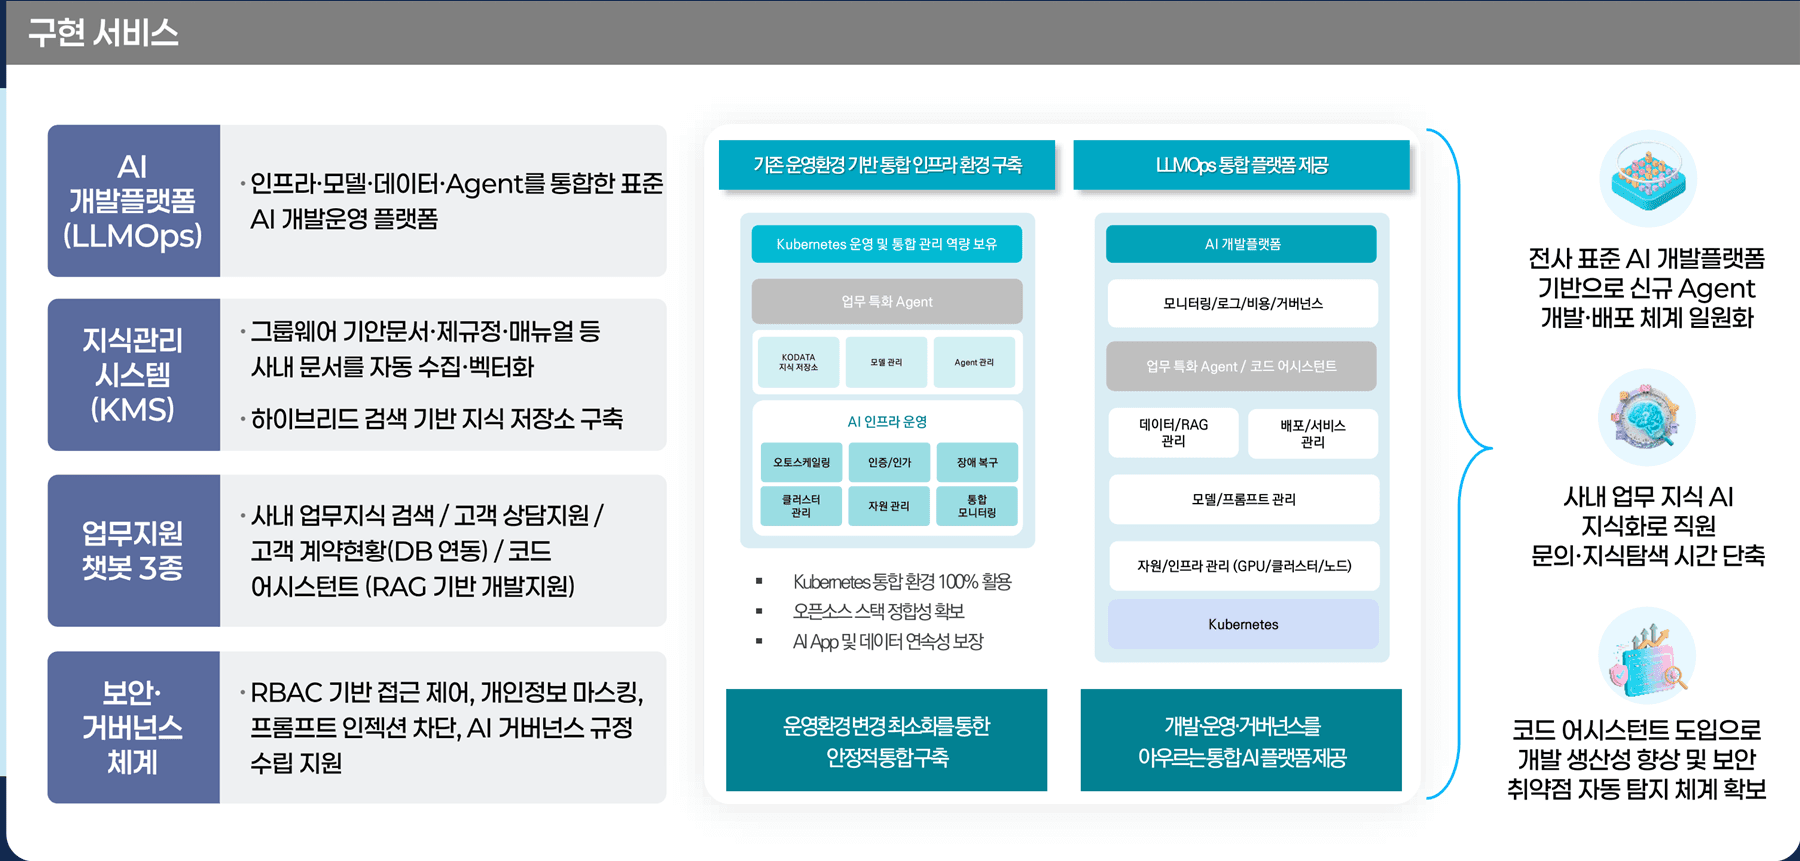
An Enterprise-Wide Standard AI Development Platform (LLMOps + KMS)
A standard AI development and operations platform was built on an H200-based Kubernetes environment, bringing infrastructure, models, data, and Agents together. Thirteen AI Agents that had been developed project by project now share one development and deployment system.
AURDA Suite
One System, from Resources to Usage Control
AI Infra + AI Gateway
AI Infra Runs Resources and Serving; AI Gateway Runs Access and Control
AURDA AI Infra runs GPU and NPU resources and model and Agent serving. AURDA AI Gateway handles access, control, and integration. MCP servers are registered, deployed, and versioned in AI Gateway, which also controls their access rights and calls. Deploy them separately or together; AI Gateway also runs on its own in a third-party GPU environment.
This download is a product brochure (PDF). We do not distribute software installers.To see the product in action, please reach us through Contact Sales.
Download
AURDA Product Overview
Considering Uracle?
From a product demo to a quote, a consultant will get back to you within one business day.
Contact Sales